Computer Vision
Annotated image, video, 3D and LiDAR data for computer vision models, from first-pass labelling to QA and correction of existing datasets.
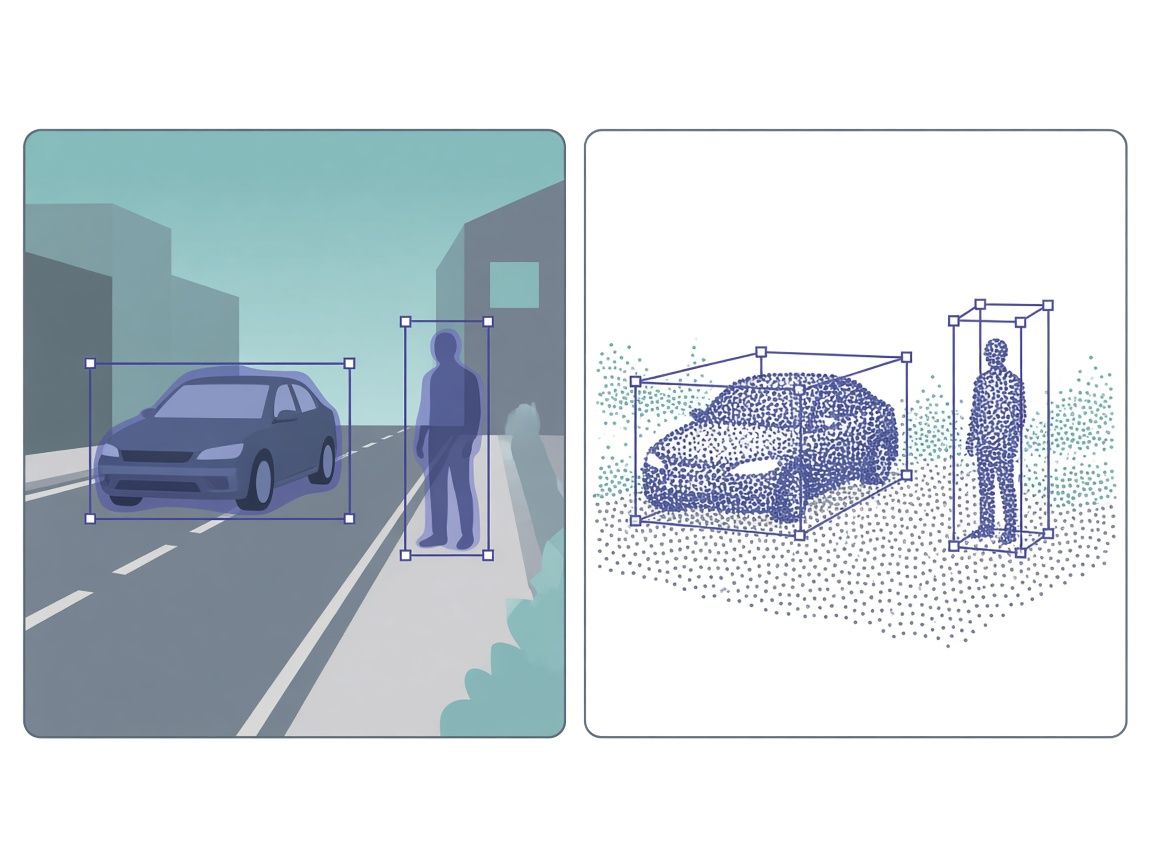
Who it is for

Teams that need annotated image, video or 3D data to train, evaluate or refresh computer vision models: start-ups preparing a first dataset, production teams running continuous labelling, and platforms that need a reviewed, managed workforce behind their tooling.
Supported tasks

We offer the following computer vision annotation operations. Each can carry the attributes your model needs, such as occlusion, visibility or colour classes, and can be applied to single images or to video.
- Image and video classification
- Bounding boxes
- Polygons
- Semantic and instance segmentation
- Lines and splines
- Keypoints and pose
- 3D and point-cloud annotation
LiDAR and multi-sensor work

We carry out LiDAR point-cloud annotation, QA and correction, including MCAP data as used with Foxglove. That covers creating new cuboids and segmentation as well as reviewing and fixing labels produced by another team or by a model.
We also handle camera and LiDAR fusion, keeping labels consistent across sensors and over time. For perception and robotics programmes, see Autonomous vehicles and robotics; for formats and MCAP handling, see Tools and Delivery.
Sample output and rubric

For each project we can share a permission-cleared or clearly synthetic example that shows four things side by side:
- Task: what the annotator was asked to do.
- Labels: the classes and attributes applied.
- Review criteria: the rubric a reviewer checks the work against.
- Format: how the output is delivered.
That way you can judge the output before committing to volume.
Relevant case studies

See how these tasks run on real programmes, from seventeen-keypoint pose to waste-stream segmentation.
- Human pose keypoint annotation: skeletons with visibility and occlusion rules.
- PPE compliance: region-of-interest tags by body region and colour.
- Queue head detection: QA and correction on fisheye CCTV.
- Retail surveillance AI: boxes plus timestamped events.
- Waste stream classification: instance segmentation on conveyor imagery.
- Workplace safety object detection: a detailed vehicle and object taxonomy.
- Autonomous vehicles and robotics: LiDAR, multi-sensor and robotics work.
Tools, handoff and QA

We work in established annotation platforms, including Encord, Roboflow, CVAT, Supervisely and Darwin (V7), or in your own tooling, and we review work before it is handed back. See Tools and Delivery for tools and formats, and How We Work for the full method.
FAQ

- Can we start with a pilot?
- Yes. We can scope a smaller first batch so you can check the labels against your guidelines before production volume.
- How do you control quality?
- Annotators work to an agreed taxonomy and edge-case rules, and their work is reviewed before delivery; on many projects we run two-tier review.
- Can you work in our tool?
- Yes. We have worked in Encord, Roboflow, CVAT, Supervisely and Darwin (V7), and with MCAP data as used with Foxglove.
- How is a project quoted?
- Each quote is specific to the project, based on complexity, specialisation, quality requirements and urgency. See Pricing.
Request a Project Quote

Send us your modality, volume, taxonomy and quality target, plus any tooling constraints such as MCAP data or a client platform, and we will scope the computer vision work with you.